| Filename | Latest commit message | Latest commit date |
|---|---|---|
 023f1fd233 * fix(map-server): simplify location update message format * fix(say-server): pass host to streamable_http_app for non-localhost deployments * refactor(pdf-server): simplify to stateless range-query architecture - Remove caching/indexing in favor of direct HTTP Range requests - Use HEAD requests to get file size (no full download) - Use Range requests to proxy byte chunks (no caching) - Local files: fs.read with offset/length - Remote files: HTTP Range header - Zero memory footprint (no PDF caching) - Truly stateless (no session management needed) - Single server.ts (~350 lines) + main.ts CLI entry point - Instant startup (no preloading) - Security: whitelist local files, allowed origins Removed files: - src/pdf-indexer.ts - src/pdf-loader.ts - src/types.ts * feat(pdf-server): add dark mode support - Add CSS variables with light-dark() function for automatic theme switching - Sync theme with host via applyDocumentTheme() - Apply host CSS variables via applyHostStyleVariables() * feat(pdf-server): add list_pdfs tool back Lists local files and allowed remote origins. Also moves CHUNK_SIZE to module level constant. * feat(pdf-server): improve tool descriptions and increase context limit - display_pdf: list all allowed domains in description - Increase MAX_MODEL_CONTEXT_LENGTH to 15000 - Move CHUNK_SIZE to module level constant * chore(say-server): remove deployment docs from repo Keep server.py fix for non-localhost deployments. Deployment docs kept locally but not in repo. * refactor(pdf-server): simplify updateModelContext format - Add widget ID for multi-widget disambiguation - Use concise header: 'PDF viewer (id) | title | Current Page: X/Y' - Add 'Page content:' prefix before text - Keep selection markers (<pdf-selection>...</pdf-selection>) * refactor: rename widgetUUID to viewUUID for consistency Aligns with main's standardization on 'view' terminology (PR #325). Also dynamically generate allowed domains in display_pdf description. * viewUUID * fix(map-server): fix syntax error in location update message * fix(pdf-server): restore package.json, improve server docs - Restore --external pdfjs-dist in build - Rewrite server.ts header for newcomers (list tools, not implementation details) - Minimize main.ts diff * chore(pdf-server): remove unused addAllowedOrigin/addAllowedLocalFile * docs(pdf-server): update README for new architecture * docs(pdf-server): restore full README, add theming section, remove get_pdf_info * rm * fix(pdf-server): restore createMcpExpressApp and error handling - Use createMcpExpressApp for DNS rebinding protection - Restore error callback in app.listen() * fix(say-server): pass host to streamable_http_app for non-localhost deployments * chore(say-server): remove deployment docs from repo * widgetId->tool id * fix(map-server): add null check for center in location update chore(pdf-server): dedupe and sort allowed origins * fix(map-server): use transparent background for rounded corners * prettier |
||
| .. | ||
| .gitignore | ||
| grid-cell.png | ||
| mcp-app.html | ||
| package.json | ||
| README.md | ||
| screenshot.png | ||
| server.py | ||


Say Server - Streaming TTS MCP App
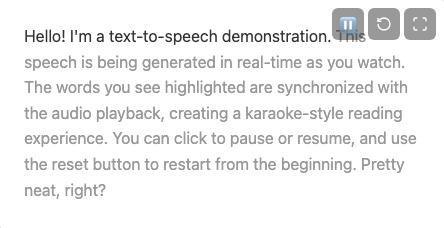
A real-time text-to-speech MCP App with karaoke-style text highlighting, powered by Kyutai's Pocket TTS.
MCP Client Configuration
Add to your MCP client configuration (stdio transport):
{
  "mcpServers": {
    "say": {
      "command": "uv",
      "args": [
        "run",
        "--default-index",
        "https://pypi.org/simple",
        "https://raw.githubusercontent.com/modelcontextprotocol/ext-apps/refs/heads/main/examples/say-server/server.py",
        "--stdio"
      ]
    }
  }
}
MCP App Features Demonstrated
This example showcases several MCP App capabilities:
- Single-file executable: Python server with embedded React UI - no build step required
- Partial tool inputs (
ontoolinputpartial): The view receives streaming text as it's being generated - Queue-based streaming: Demonstrates how to stream text out and audio in via a polling tool (adds text to an input queue, retrieves audio chunks from an output queue)
- Model context updates: The view updates the LLM with playback progress ("Playing: ...snippet...")
- Native theming: Uses CSS variables for automatic dark/light mode adaptation
- Fullscreen mode: Toggle fullscreen via
requestDisplayMode()API, press Escape to exit - Multi-view speak lock: Coordinates multiple TTS views via localStorage so only one plays at a time
- Hidden tools (
visibility: ["app"]): Private tools only accessible to the view, not the model - External links (
openLink): Attribution popup usesapp.openLink()to open external URLs - CSP metadata: Resource declares required domains (
esm.sh) for in-browser transpilation
Features
- Streaming TTS: Audio starts playing as text is being generated
- Karaoke highlighting: Words are highlighted in sync with speech
- Interactive controls: Click to pause/resume, double-click to restart
- Low latency: Uses a polling-based queue for minimal delay
Prerequisites
- uv - fast Python package manager
Quick Start
The server is a single self-contained Python file that can be run directly from GitHub:
# Run directly from GitHub (uv auto-installs dependencies)
uv run https://raw.githubusercontent.com/modelcontextprotocol/ext-apps/main/examples/say-server/server.py
The server will be available at http://localhost:3109/mcp.
Running with Docker
Run directly from GitHub using the official uv Docker image:
docker run --rm -it \
  -p 3109:3109 \
  -v ~/.cache/huggingface-docker-say-server:/root/.cache/huggingface \
  ghcr.io/astral-sh/uv:debian \
  uv run https://raw.githubusercontent.com/modelcontextprotocol/ext-apps/main/examples/say-server/server.py
Usage
With Claude Desktop
Add to your Claude Desktop config (~/Library/Application Support/Claude/claude_desktop_config.json):
{
  "mcpServers": {
    "say": {
      "command": "uv",
      "args": [
        "run",
        "https://raw.githubusercontent.com/modelcontextprotocol/ext-apps/main/examples/say-server/server.py",
        "--stdio"
      ]
    }
  }
}
With MCP Clients
Connect to http://localhost:3109/mcp and call the say tool:
{
  "name": "say",
  "arguments": {
    "text": "Hello, world! This is a streaming TTS demo."
  }
}
Available Voices
The default voice is cosette. Use the list_voices tool or pass a voice parameter to say:
Predefined Voices
alba,marius,javert,jean- from alba-mackenna (CC BY 4.0)cosette,eponine,azelma,fantine- from VCTK dataset (CC BY 4.0)
Custom Voices
You can also use HuggingFace URLs or local file paths:
{"text": "Hello!", "voice": "hf://kyutai/tts-voices/voice-donations/alice.wav"}
{"text": "Hello!", "voice": "/path/to/my-voice.wav"}
See the kyutai/tts-voices repository for more voice collections
Architecture
The entire server is contained in a single server.py file:
saytool: Public tool that triggers the view with text to speak- Private tools (
create_tts_queue,add_tts_text,poll_tts_audio, etc.): Hidden from the model, only callable by the view - Embedded React view: Uses Babel standalone for in-browser JSX transpilation - no build step needed
- TTS backend: Manages per-request audio queues using Pocket TTS
The view communicates with the server via MCP tool calls:
- Receives streaming text via
ontoolinputpartialcallback - Incrementally sends new text to the server as it arrives (via
add_tts_text) - Polls for generated audio chunks while TTS runs in parallel
- Plays audio via Web Audio API with synchronized text highlighting
Multi-view Speak Lock
When multiple TTS views exist in the same browser (e.g., multiple chat messages each with their own say view), they coordinate via localStorage to ensure only one plays at a time:
- Unique view IDs: Each view receives a UUID via
toolResult._meta.viewUUID - Announce on Play: When starting, a view writes
{uuid, timestamp}tolocalStorage["mcp-tts-playing"] - Poll for Conflicts: Every 200ms, playing views check if another view took the lock
- Yield Gracefully: If another view started playing, pause and yield
- Clean Up: On pause/finish, clear the lock (only if owned)
This "last writer wins" protocol ensures a seamless experience: clicking play on any view immediately pauses others, without requiring cross-iframe postMessage coordination.
TODO
- Persist caret position in localStorage (resume from where you left off)
- Click anywhere in text to move the cursor/playback position
Credits
This project uses Pocket TTS by Kyutai - a fantastic open-source text-to-speech model. Thank you to the Kyutai team for making this technology available!
The server includes modified Pocket TTS code to support streaming text input (text can be fed incrementally while audio generation runs in parallel). A PR contributing this functionality back to the original repo is planned.
License
This example is MIT licensed.
Third-Party Licenses
This project uses the following open-source components:
| Component | License | Link |
|---|---|---|
| pocket-tts | MIT | Python TTS library |
| Kyutai TTS model | CC-BY 4.0 | Text-to-speech model weights |
| kyutai/tts-voices | Mixed (see below) | Voice prompt files |
Voice Collection Licenses
The predefined voices in this example use CC-BY 4.0 licensed collections:
| Collection | License | Commercial Use |
|---|---|---|
| alba-mackenna | CC-BY 4.0 | ✅ Yes (with attribution) |
| vctk | CC-BY 4.0 | ✅ Yes (with attribution) |
| cml-tts/fr | CC-BY 4.0 | ✅ Yes (with attribution) |
| voice-donations | CC0 (Public Domain) | ✅ Yes |
| expresso | CC-BY-NC 4.0 | ❌ Non-commercial only |
| ears | CC-BY-NC 4.0 | ❌ Non-commercial only |
⚠️ Note: If you use voices from the expresso/ or ears/ collections, your use is restricted to non-commercial purposes.