 298e884ec3
* chore: add stable spec release 2026-01-26

- Use git mv to copy specification from draft to specification/2026-01-26/apps.mdx (preserves history)
- Update status from 'Draft' to 'Stable (2026-01-26)'
- Add specification version table to README
- Update Resources section with links to both stable and draft specs

* chore: bump version to 1.0.0

- Update main package version from 0.4.2 to 1.0.0
- Update all example package versions to 1.0.0
- Regenerate package-lock.json

* prettier

* chore: align protocol version with spec release 2026-01-26

- Add 'Protocol Version: 2026-01-26' to spec header
- Update LATEST_PROTOCOL_VERSION from '2025-11-21' to '2026-01-26'
- Update spec examples to use '2026-01-26' protocol version
- Add '2025-11-21' to SUPPORTED_PROTOCOL_VERSIONS for backwards compatibility

* chore: update spec references to stable 2026-01-26

- Update typedoc.config.mjs navigation link
- Update docs/overview.md spec links (10 occurrences)
- Update plugins/mcp-apps/skills/create-mcp-app/SKILL.md spec link
- Update src/spec.types.ts @see links
- Update AGENTS.md spec path
- Regenerate src/generated/schema.ts with updated links

* chore: simplify versioning - first stable release

- Remove backwards compatibility version (2025-11-21) - this is the first stable release
- Remove redundant 'Protocol Version' header - spec version IS the protocol version

* chore: add history reference comment to stable spec
3.1 KiB
3.1 KiB
Transcript Server
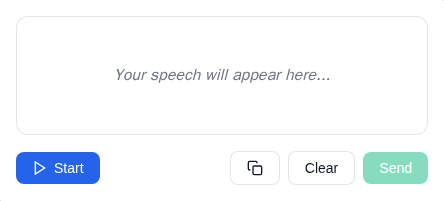
An MCP App Server for live speech transcription using the Web Speech API.
MCP Client Configuration
Add to your MCP client configuration (stdio transport):
{
  "mcpServers": {
    "transcript": {
      "command": "npx",
      "args": [
        "-y",
        "--silent",
        "--registry=https://registry.npmjs.org/",
        "@modelcontextprotocol/server-transcript",
        "--stdio"
      ]
    }
  }
}
Local Development
To test local modifications, use this configuration (replace ~/code/ext-apps with your clone path):
{
  "mcpServers": {
    "transcript": {
      "command": "bash",
      "args": [
        "-c",
        "cd ~/code/ext-apps/examples/transcript-server && npm run build >&2 && node dist/index.js --stdio"
      ]
    }
  }
}
Features
- Live Transcription: Real-time speech-to-text using browser's Web Speech API
- Transitional Model Context: Streams interim transcriptions to the model via
ui/update-model-context, allowing the model to see what the user is saying as they speak - Audio Level Indicator: Visual feedback showing microphone input levels
- Send to Host: Button to send completed transcriptions as a
ui/messageto the MCP host - Start/Stop Control: Toggle listening on and off
- Clear Transcript: Reset the transcript area
Setup
Prerequisites
- Node.js 18+
- Chrome, Edge, or Safari (Web Speech API support)
Installation
npm install
Running
# Development mode (with hot reload)
npm run dev

# Production build and serve
npm run start
Usage
The server exposes a single tool:
transcribe
Opens a live speech transcription interface.
Parameters: None
Example:
{
  "name": "transcribe",
  "arguments": {}
}
How It Works
- Click Start to begin listening
- Speak into your microphone
- Watch your speech appear as text in real-time (interim text is streamed to model context via
ui/update-model-context) - Click Send to send the transcript as a
ui/messageto the host (clears the model context) - Click Clear to reset the transcript
Architecture
transcript-server/
├── server.ts          # MCP server with transcribe tool
├── server-utils.ts    # HTTP transport utilities
├── mcp-app.html       # Transcript UI entry point
├── src/
│   ├── mcp-app.ts     # App logic, Web Speech API integration
│   ├── mcp-app.css    # Transcript UI styles
│   └── global.css     # Base styles
└── dist/              # Built output (single HTML file)
Notes
- Microphone Permission: Requires
allow="microphone"on the sandbox iframe (configured viapermissions: { microphone: {} }in the resource_meta.ui) - Browser Support: Web Speech API is well-supported in Chrome/Edge, with Safari support. Firefox has limited support.
- Continuous Mode: Recognition automatically restarts when it ends, for seamless transcription
Future Enhancements
- Language selection dropdown
- Whisper-based offline transcription (see TRANSCRIPTION.md)
- Export transcript to file
- Timestamps toggle